
How to Read A/B Test Results: the Verdict, the Lift, the Confidence and the Range
An A/B test ends in a handful of numbers, and most bad calls come from reading the wrong one: stopping the moment a line crosses 95%, trusting a big lift with a range that runs through zero, or crowning a winner on a metric nobody chose. This is how to read a result in the order that keeps you out of trouble — with a real result from the Personyze panel as the example.
A click, a signup, a purchase — decided before the test starts, not after.
Then the lift, how sure the test is, and the range the real difference lies in.
One overall winner can hide a different winner on phones.
Start with what the test is judged on
Before any number, check the metric. A test is only as good as the goal it is decided on, and the goal has to be the one that matters to the business — not whichever metric happens to move. A test can look like a clear loss on search clicks while purchases do not change at all.
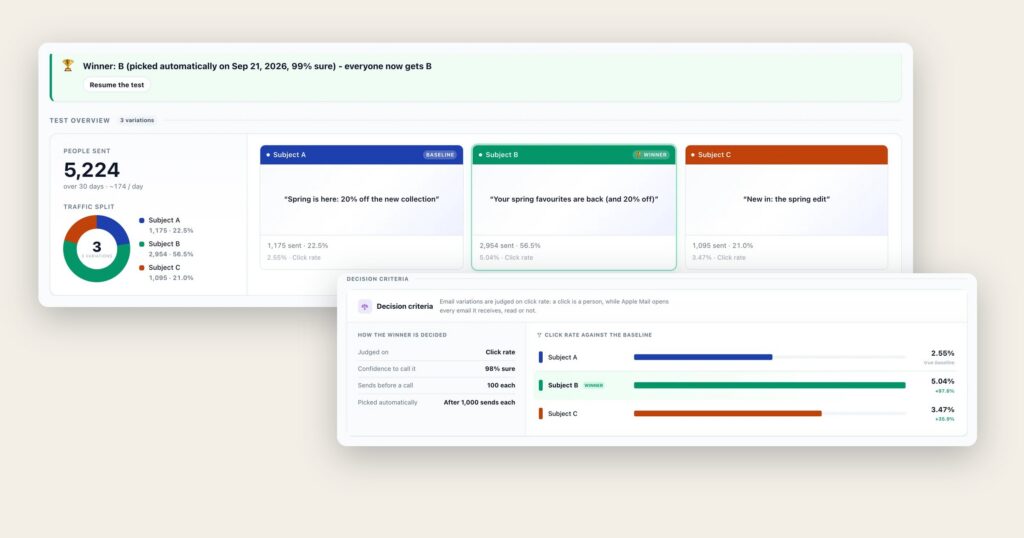
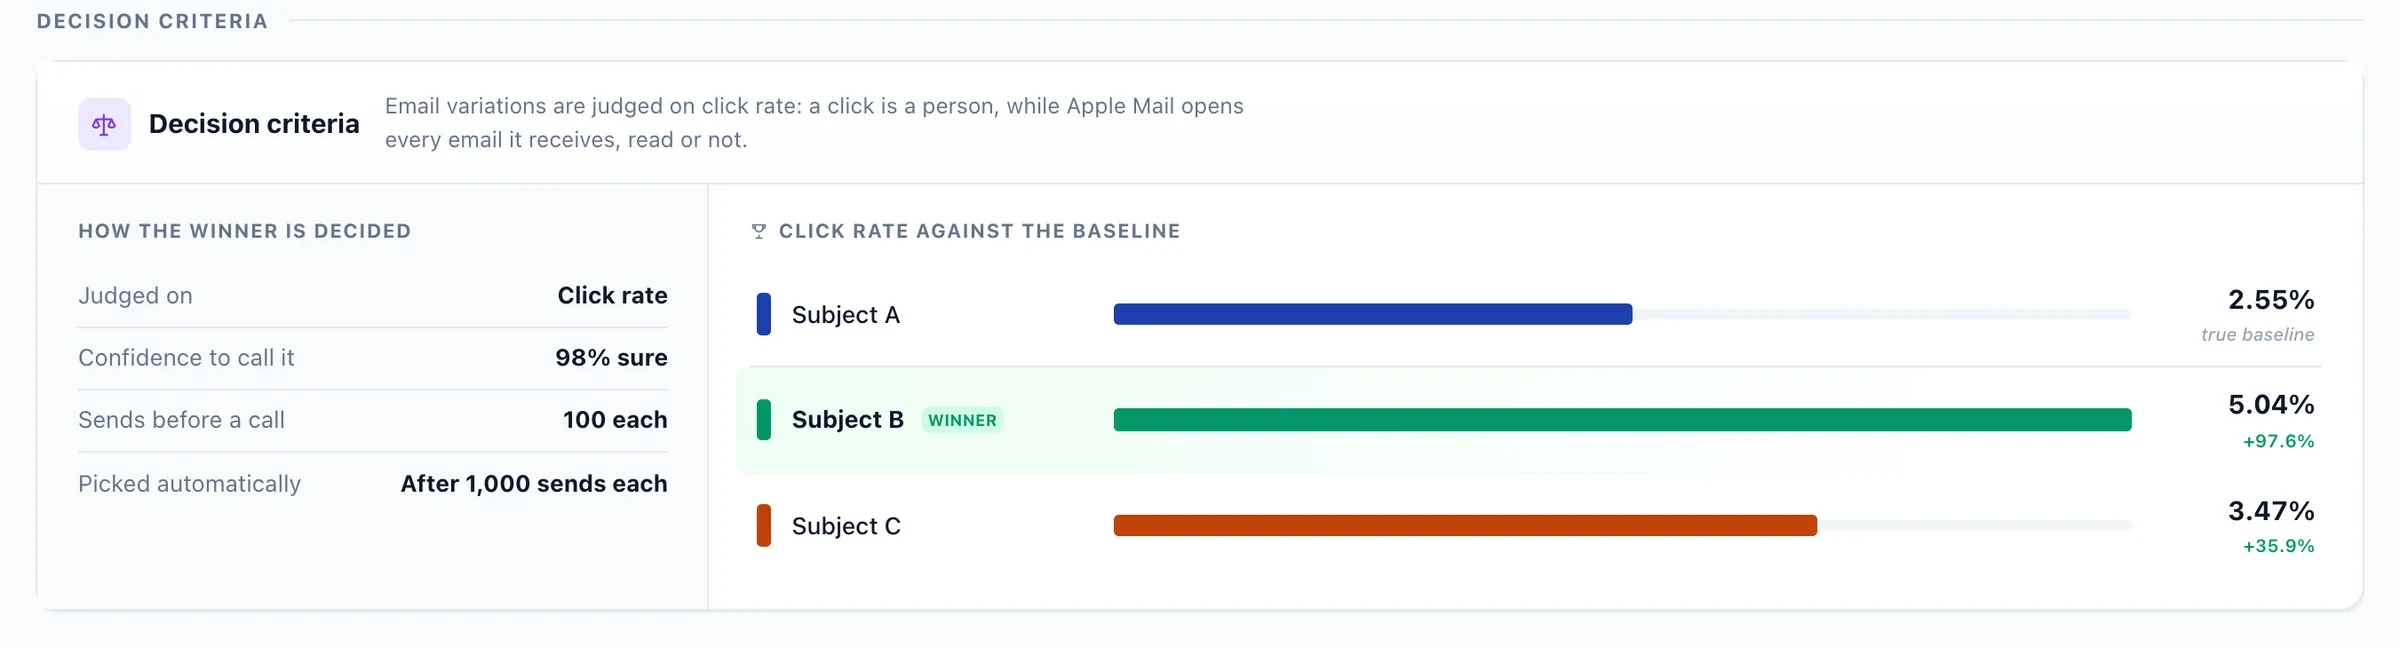
In Personyze a test is judged on the goal you name for it. If it names none, it is judged on purchases; if your account records no purchases, on the rate of any goal. For an email, the goal is clicks, not opens: Apple Mail opens every email it receives, read or not, so an open rate measures the mail app as much as the reader.
Read the verdict first
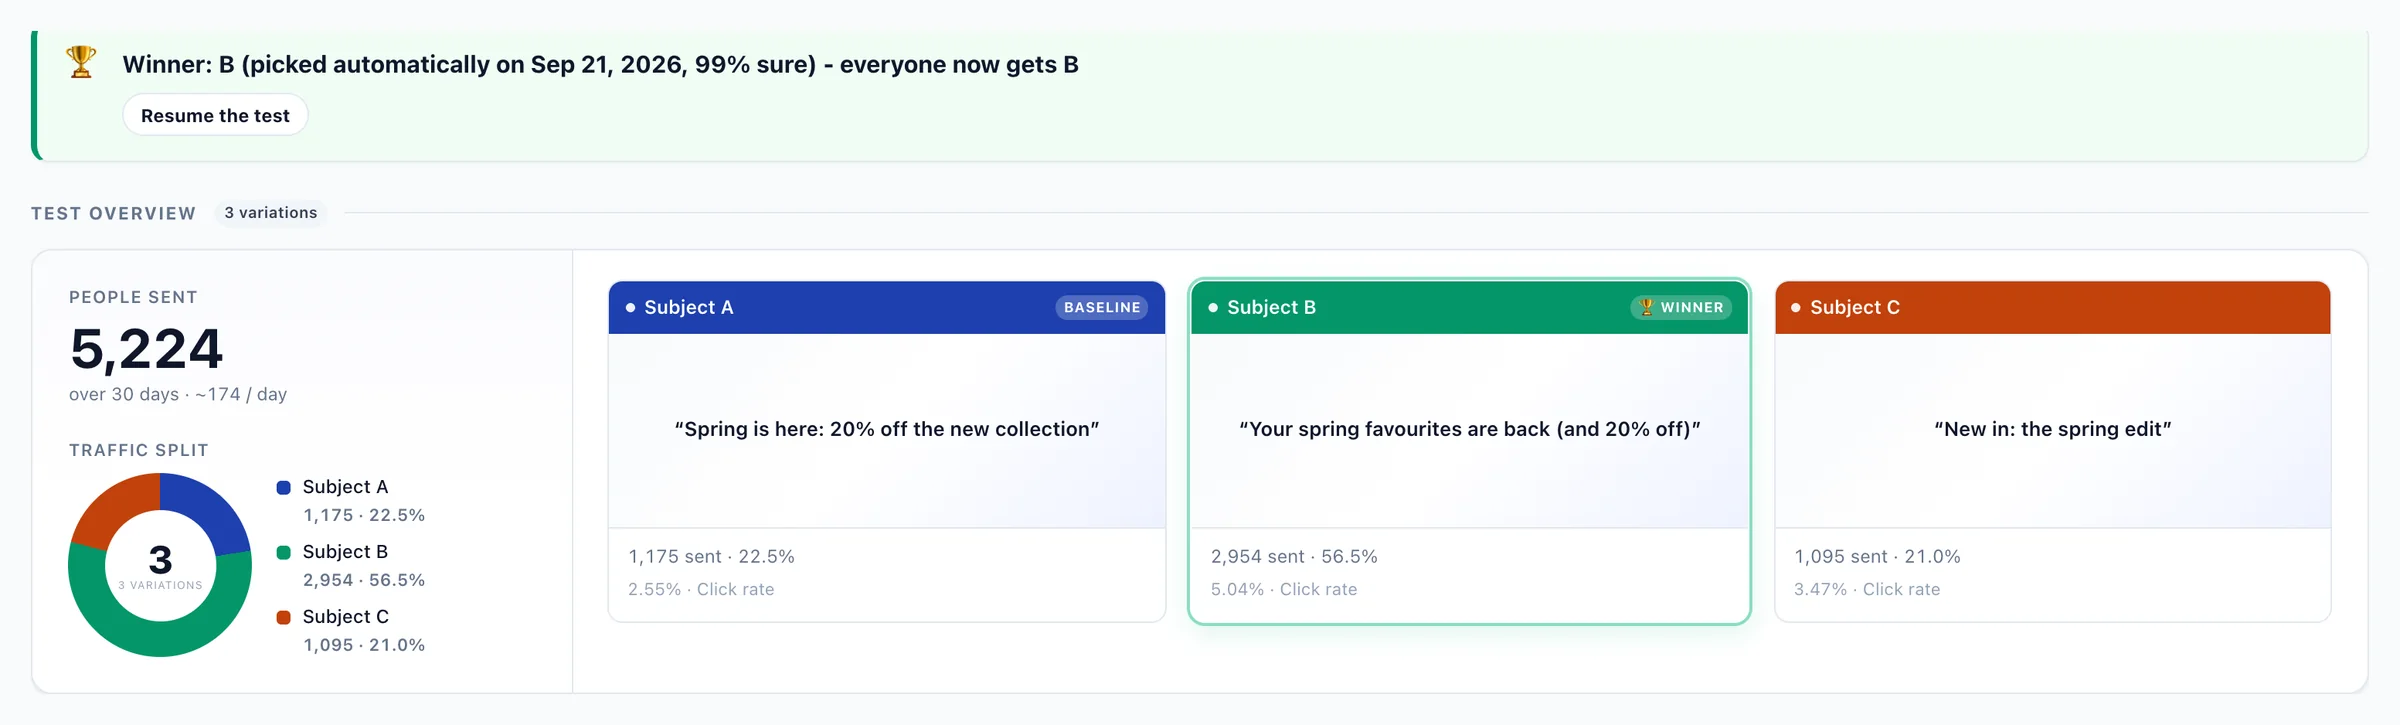
A finished result says one of three things, and it says it in a sentence before it shows a chart:
- A winner — one version beat the baseline with the confidence you asked for.
- Keep the original — no version beat it. That is a result, not a failure: you learned what not to ship.
- Keep running — nothing is sure yet. The honest answer is to wait, not to pick the one that is ahead.
The lift, and how sure the test is
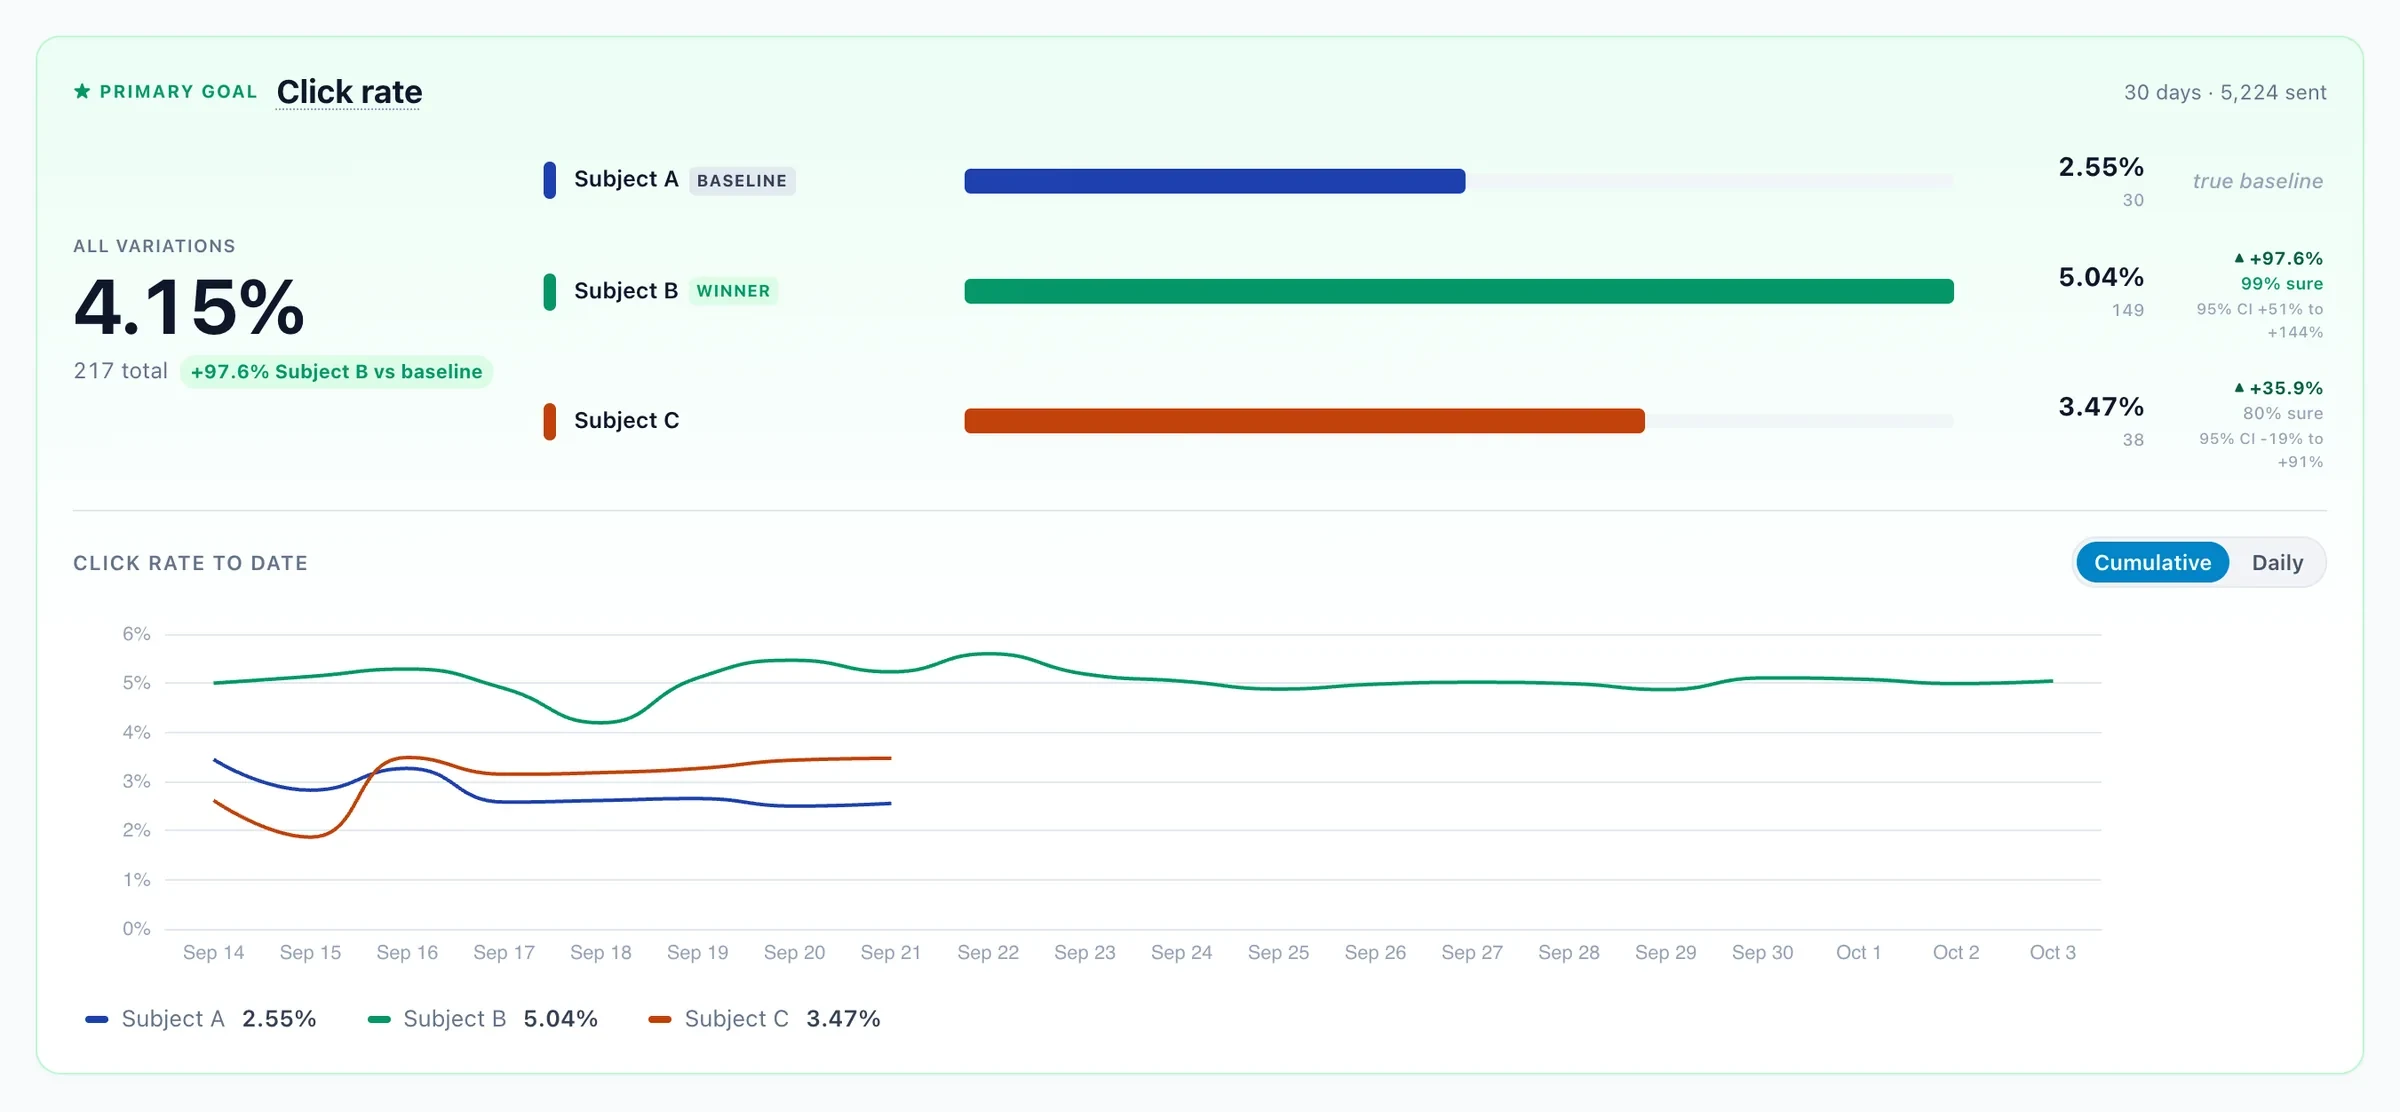
The lift is how far a version is ahead of (or behind) the baseline: Subject B’s click rate of 5.04% against A’s 2.55% is a lift of +97.6%. The confidence beside it is how sure the test is that the gap is real rather than the luck of who happened to arrive in each group — here, 99%.
Two habits make the confidence trustworthy. Decide the level before you start — 95% is common, stricter tests ask for more — and do not stop the first time a line touches it. Early in a test the numbers swing; a version can cross 95% on Tuesday and fall back by Friday.
Then read the range — this is where most mistakes hide
Under each lift sits a range: where the real difference most likely lies (a 95% interval). It is the most useful number on the screen, because it tells you the worst case as well as the best.
The scale runs from −50% to +150%; the black line is no difference. B’s range (+51% to +144%) sits wholly to the right of it: B is better, by at least half. C’s range (−19% to +91%) crosses it: C might be better or worse, so its +35.9% is not a result yet.
Read the low end of the range as the honest promise. B’s range says it is better by at least half; the headline +97.6% is only the middle of it. And a version whose range crosses zero has not been shown to be better at all, however big its lift looks.
Check when it became clear
The rate over time shows whether a lead was steady or a spike. A version that led from the first days and kept leading is a stronger result than one that pulled ahead in the last two. Run a test for whole weeks, so weekdays and weekends both count, and be wary of a lift that shrinks every day — the novelty of a change can wear off.
Agree the decision criteria before the test starts
Most arguments about a result are really arguments about the rules. Set them first: what the test is judged on, how sure it must be, how much traffic each version needs before anyone calls it, and whether the winner is picked automatically. When a test has several goals that pull in different directions, decide how much each one counts.
Last: does the winner hold for every audience?
An overall winner is an average. It can hide a different winner for a large group of your visitors — the version that loses overall can win on phones. Before you ship, look at the result by audience, and trust a difference only where it is large enough and holds up; with many audiences, one will look different by chance.
In Personyze the result names it in a line — “Variation A leads overall, but Variation B leads for phone visitors” — and you can give each audience the version that won it. The walkthrough below reads a website test from the verdict to the breakdown by audience.
A checklist for reading any A/B test
- Judged on the right goal? The one you chose before the test, not the one that moved.
- What does the verdict say? A winner, keep the original, or keep running.
- How big is the lift, and how sure? At the level you set in advance.
- Where is the range? If it crosses zero, it is not a result yet. Read its low end as the promise.
- When did it become clear? Steady from early on, over whole weeks.
- For whom? Check the audiences before you ship one version to everyone.
Questions people ask
What does “99% sure” mean in an A/B test result?
It is how confident the test is that the gap between a version and the baseline is real, not the chance of who happened to land in each group. Set the level you need before the test starts, and do not stop the first time a result touches it.
What is the range shown under each result?
The interval where the real difference most likely lies — a 95% range. If it sits wholly above zero, the version is better, by at least its low end. If it crosses zero, the version has not been shown to be better or worse yet.
How long should an A/B test run?
Until each version has the traffic your decision criteria ask for and the result reaches the confidence you set — and for whole weeks, so weekday and weekend visitors both count.
Should an email A/B test be judged on opens?
No. Apple Mail opens every email it receives, read or not, so open rates are inflated for a large share of readers. Judge email tests on clicks, which only a person makes.
Can different audiences have different winners?
Yes. The version that wins overall can lose for a big group, such as phone visitors. Look at the result by audience and, where a difference is large and holds up, give that audience the version it preferred.
Book a demo with a personalization expert
30 minutes with a personalization expert. Bring your stack, your goals, your skepticism. We'll show you what changes when every visit feels like the only one.